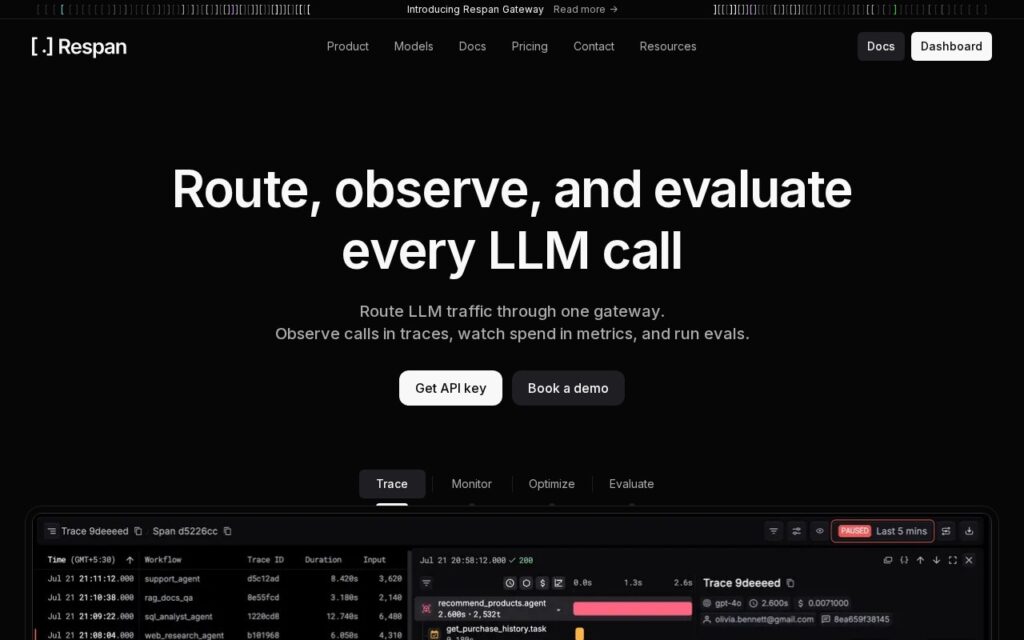
Respan is LLM infrastructure from Keywords AI. A gateway routes traffic through a single endpoint to more than a thousand models with automatic fallbacks and response caching, observability traces every call, tool run and agent action with latency, cost and token detail, and evaluations score outputs with LLM judges, deterministic checks or human review.
Automatic fallback is the unglamorous feature that earns its keep. Model providers have outages, rate limits arrive without warning, and an application whose only route to a model is one provider’s endpoint fails whenever that provider does. Rerouting mid-incident is the difference between degraded and down.
The Y Combinator company reports more than 80 trillion tokens processed. It starts free with no published tiers, so cost at production volume is unknown until you ask. A gateway is another hop in the request path and its own dependency, and LLM-judge evaluation inherits the judgement of the model doing the judging.
Key features
Single gateway endpoint to 1,000-plus models
Automatic fallbacks and response caching
Tracing of every call, tool run and agent action
Evaluations by LLM judge, deterministic check or human review
Cost, latency and token monitoring with alerts
Screenshots & demo
Pricing
Respan offers a free plan, with paid upgrades for higher limits and more features.
One API routes to 500+ AI models across 50+ providers – OpenAI, Anthropic, Google, AWS, Cohere and more – with automatic fallback if a provider goes down, no markup on the underlying cost.