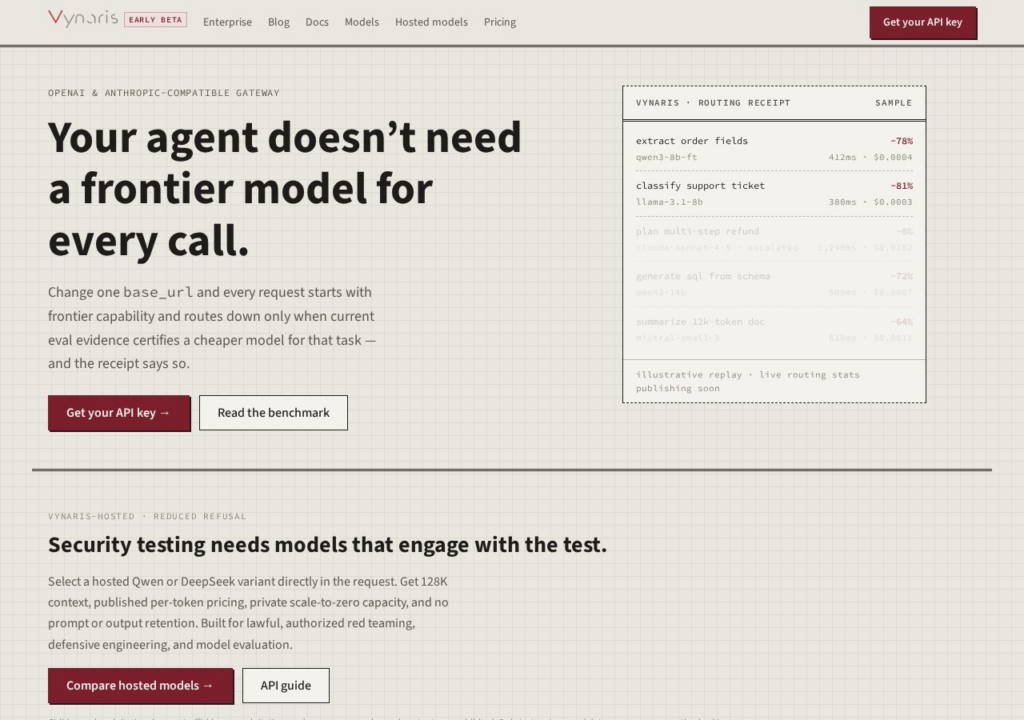
Vynaris is an LLM gateway that cuts model costs by routing. Point an application at it by changing one base_url, since it is compatible with the OpenAI and Anthropic APIs, and each request starts with frontier-model capability, then routes down to a cheaper model only when current evaluation evidence certifies that model for the task. Every call returns a receipt showing which model served it, the latency and the cost, so the routing is auditable rather than a black box. Requests no cheap model can handle escalate to a frontier model. Pay-as-you-go pricing is the provider's list price plus a 3% fee, falling to 1% above $500 of monthly usage, and fixed plans from $45 add access to privately hosted models, including unfiltered ones aimed at security testing. It is in early beta, and the saving depends entirely on how much of your traffic a smaller model can take.
ZeroGPU
3.8Cuts inference cost by routing repeatable tasks to smaller specialised models on an edge network.