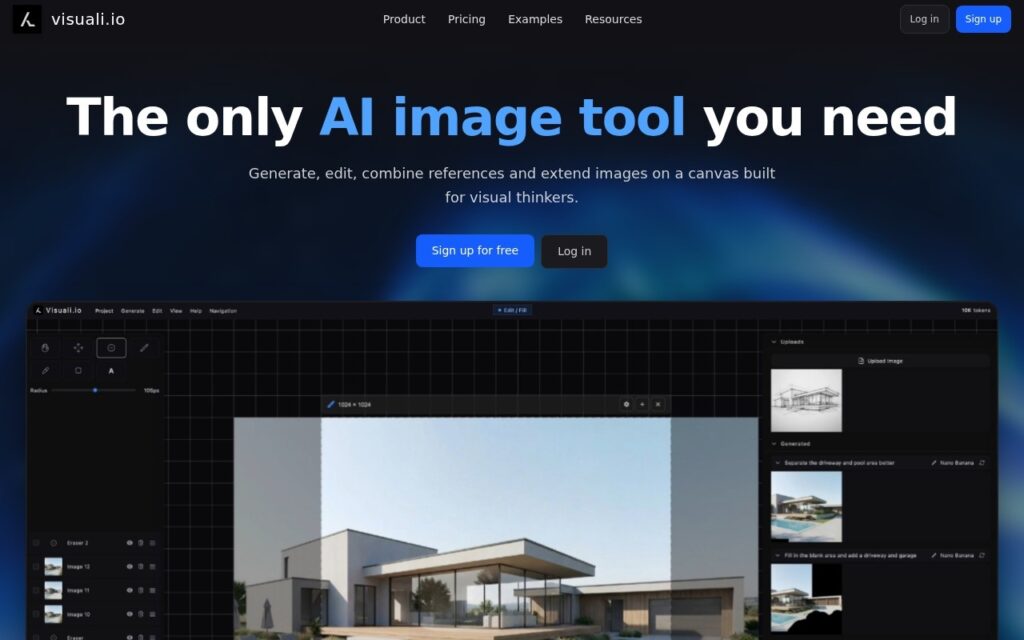
Visuali is a browser-based canvas for generating and editing images with AI, made by Visuali AS in Oslo, Norway. Prompts, reference images and masks all work on one infinite canvas with layers, drawing, text and shapes, and an AI agent can generate, edit and lay out images from a written instruction. It reaches several image model families from the same workspace, including GPT Image, Nano Banana, Seedream, Flux and Stable Diffusion XL.
Putting the models behind one canvas is the useful idea. Comparing how different models handle the same prompt and reference normally means separate accounts and separate exports; here each generation is listed with the model that made it, and fill, extend and inpainting tools work on whichever result you keep. The homepage demo takes an architectural sketch to renders and then adjusts the driveway and pool placement with follow-up instructions, which is the iterative, reference-led workflow a canvas suits better than a one-shot prompt box.
Usage is metered in tokens rather than images. After a 7-day trial the plans are Starter at $20 a month for 1,000 tokens, Pro at $60 for 3,000, Studio at $200 for 10,000, and an Unlimited tier by quote, all with access to every model. Work out the token cost of your usual model and image size before choosing a plan. The product is new, with a 2026 copyright and no named customers, and there is no free tier once the trial ends.