You hit Enter, and an AI tool answers in a few seconds, but the model only did part of that work. AI infrastructure is everything else. It’s the DNS, load balancers, APIs, databases, GPU servers, networks and IP addresses that carry your prompt to the model and bring the answer back to you.
Good software hides all of that. The reality is messier.
Before a large language model generates a single token, your request has been routed, authenticated, assigned to a server with spare capacity, and paired with stored data such as your conversation history.
Only then does the model start the part most people call artificial intelligence.
AI coverage fixates on models: reasoning benchmarks, context windows, parameter counts, inference speed. Those gains are real. But they’ve created the impression that a better AI tool means a better model and nothing else.
Anyone who ships AI products knows that’s only half the story.
Why Is the Model Only Part of the Product?
Picture two AI writing assistants built on the same language model. One answers in under two seconds, the other in eight or nine. Most of that gap has nothing to do with the model, which is why cutting inference latency has become its own engineering discipline.
On paper, they’re equally intelligent. To the person typing, they’re different products.
People don’t separate model performance from product performance. If a tool feels slow, unavailable or inconsistent, nobody asks whether the cause is networking, cloud capacity or an overloaded inference server. They decide the app isn’t very good.
That’s why AI infrastructure gets as much engineering attention as the model itself, and why two tools on the same model can feel nothing alike.
What Happens to Your Prompt After You Hit Enter?
A prompt doesn’t teleport into a GPU cluster. It passes through six broad stages, each run by a different system, before the first word of the answer reaches your screen.
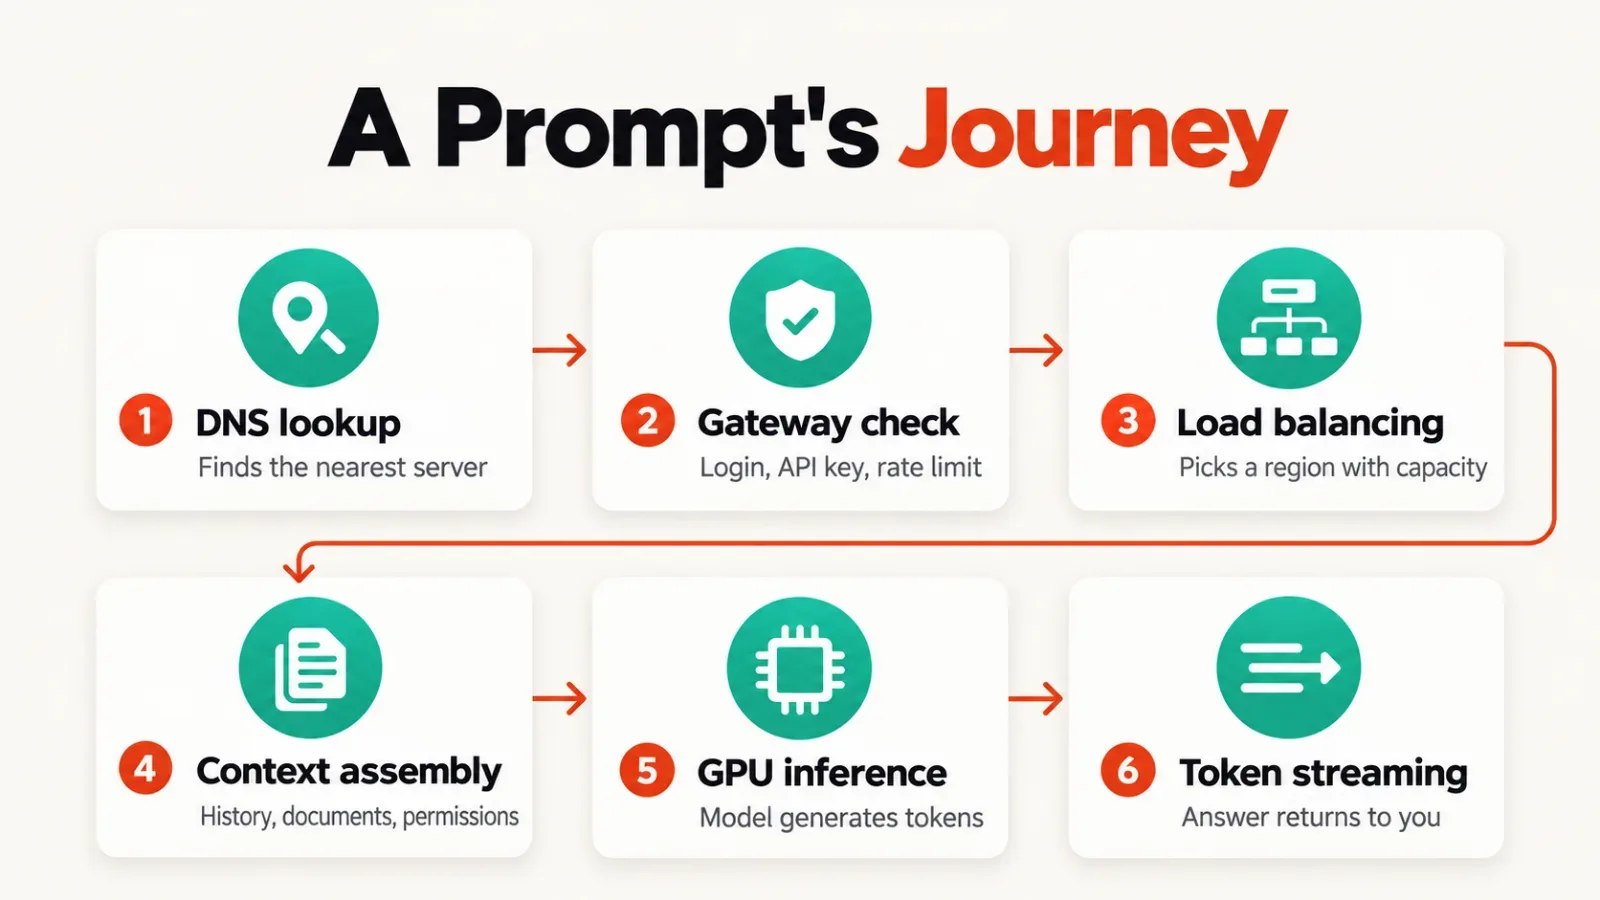
- DNS resolves the tool’s domain name to the address of a server near you.
- An edge network or API gateway checks your login, API key and rate limit.
- A load balancer sends the request to a region and server with spare capacity.
- The application gathers context: chat history, retrieved documents and permission checks.
- GPU servers run inference, the step where the model generates its answer token by token.
- The tokens stream back across the same networks to your browser or app.
Most of those stages take milliseconds.
They also run on every single request, and any one of them can be the reason a tool feels slow.
Why Is AI Turning Into a Networking Problem?
The first wave of AI startups competed on models. Many now find that scaling the AI infrastructure around the model is as hard as building the model.
Plenty of AI products launch globally from day one. One tool can draw users in London in the morning, São Paulo in the afternoon and Singapore by night. Serving one market well stops being enough, because distance starts to matter.
Distance has a physical floor: light in optical fiber covers about 200 kilometres per millisecond. A London to Singapore round trip spans more than 21,000 km of cable even on a perfect route, so it costs over 100 milliseconds before any server does any work.
Multiply that across millions of requests, and latency becomes part of the product rather than a number on an engineer’s dashboard.
That’s why large AI platforms spread workloads across regions, replicate services and keep tuning how traffic moves through their infrastructure. Users never see those decisions. They see the result, and fast answers quickly become the baseline they expect.
Ironically, the better the infrastructure performs, the less anyone thinks about it.
Also Read: Top AI Predictive Analytics Tools
Why Do Invisible Systems Shape the Visible Experience?
AI infrastructure used to sit quietly underneath the software while developers built features. In AI products, the line between the two is blurring fast.
Retrieval-augmented generation (RAG), where a model pulls in relevant documents before it answers, shows why. Before the model replies, the app searches a vector database (a store that finds text by meaning, not exact keywords), fetches documents, checks permissions and assembles the context.
Every extra component adds a dependency, another network request and another chance for delay.
Agentic tools, meaning AI systems that take actions across apps instead of only answering, add more hops. The Model Context Protocol (MCP), an open standard Anthropic introduced in November 2024, gives models one common way to call external tools and data sources.
Each of those calls is another round trip, so a tool that chains five services feels every one of them. Keep that in mind when you compare AI automation platforms side by side.
Modern AI applications behave more like distributed systems than standalone software. The intelligence comes from the model, but the experience depends on everything around it.
Internal AI deployments make that web of services bigger. A customer support assistant needs company documentation. A finance copilot queries several internal databases, and an engineering assistant talks to issue trackers, code repositories and monitoring tools through AI development services within a few seconds.
The model isn’t doing all the work. It’s coordinating a growing web of services.
Where Each Layer Shows Up for Users
Each layer of AI infrastructure fails in its own recognisable way, which helps you read what’s going wrong when a tool misbehaves.
| Layer | What it does | What you notice when it struggles |
|---|---|---|
| DNS and edge network | Points you to the nearest server | The tool won’t load at all |
| API gateway | Checks keys, logins and rate limits | “Too many requests” errors on busy days |
| Load balancer | Spreads traffic across servers and regions | Some sessions run fast while others stall |
| Retrieval and databases | Fetch chat history and documents for context | Answers that ignore your files or forget the conversation |
| GPU inference servers | Generate the answer token by token | A long wait before the first word appears |
| IP addressing | Gives every service a reachable address | Blocked requests or failed connections in new regions |
What Role Does IP Infrastructure Play in AI?
IP infrastructure is the system of addresses that lets users, services and cloud environments find each other, and every AI request depends on it. GPUs dominate the conversation about AI infrastructure, yet a GPU nobody can reach answers nobody.
Most people only meet IP addresses when fixing a home router or setting up a cloud server. In an AI product, every service that talks to another service does it through those addresses.
As AI products expand internationally, managing those addresses gets harder than most teams expect.
The reason is scarcity. IPv4, the addressing system most of the internet still runs on, uses 32-bit addresses, which caps the total at about 4.3 billion. RIPE NCC, the registry for Europe, the Middle East and parts of Central Asia, handed out its last free IPv4 block in November 2019.
IPv6 uses 128-bit addresses and removes the limit for practical purposes. But a public AI service still needs IPv4 to reach every user and partner network that hasn’t switched over.
Running workloads on several cloud providers, opening a new region or migrating between environments all raise questions that GPU capacity doesn’t answer. Which addresses will you use? Do they carry a clean reputation, or did a previous holder land them on a spam blocklist?
Since the free pools ran dry, IPv4 addresses are traded and leased on secondary markets. Companies such as IPXO let organizations lease IPv4 addresses instead of buying blocks outright.
Leasing fits a team testing a new region. Buying fits one that needs the same addresses for years, and either way, check a block’s reputation history before production traffic touches it.
Nobody advertises this layer. You only notice it when it isn’t there.
Also Read: Top AI-Powered Process Optimization Tools
How Can You Judge an AI Tool’s Infrastructure Before You Commit?
An AI tool’s infrastructure shows in six signals you can check during a free trial or a sales call, long before you sign an annual contract.
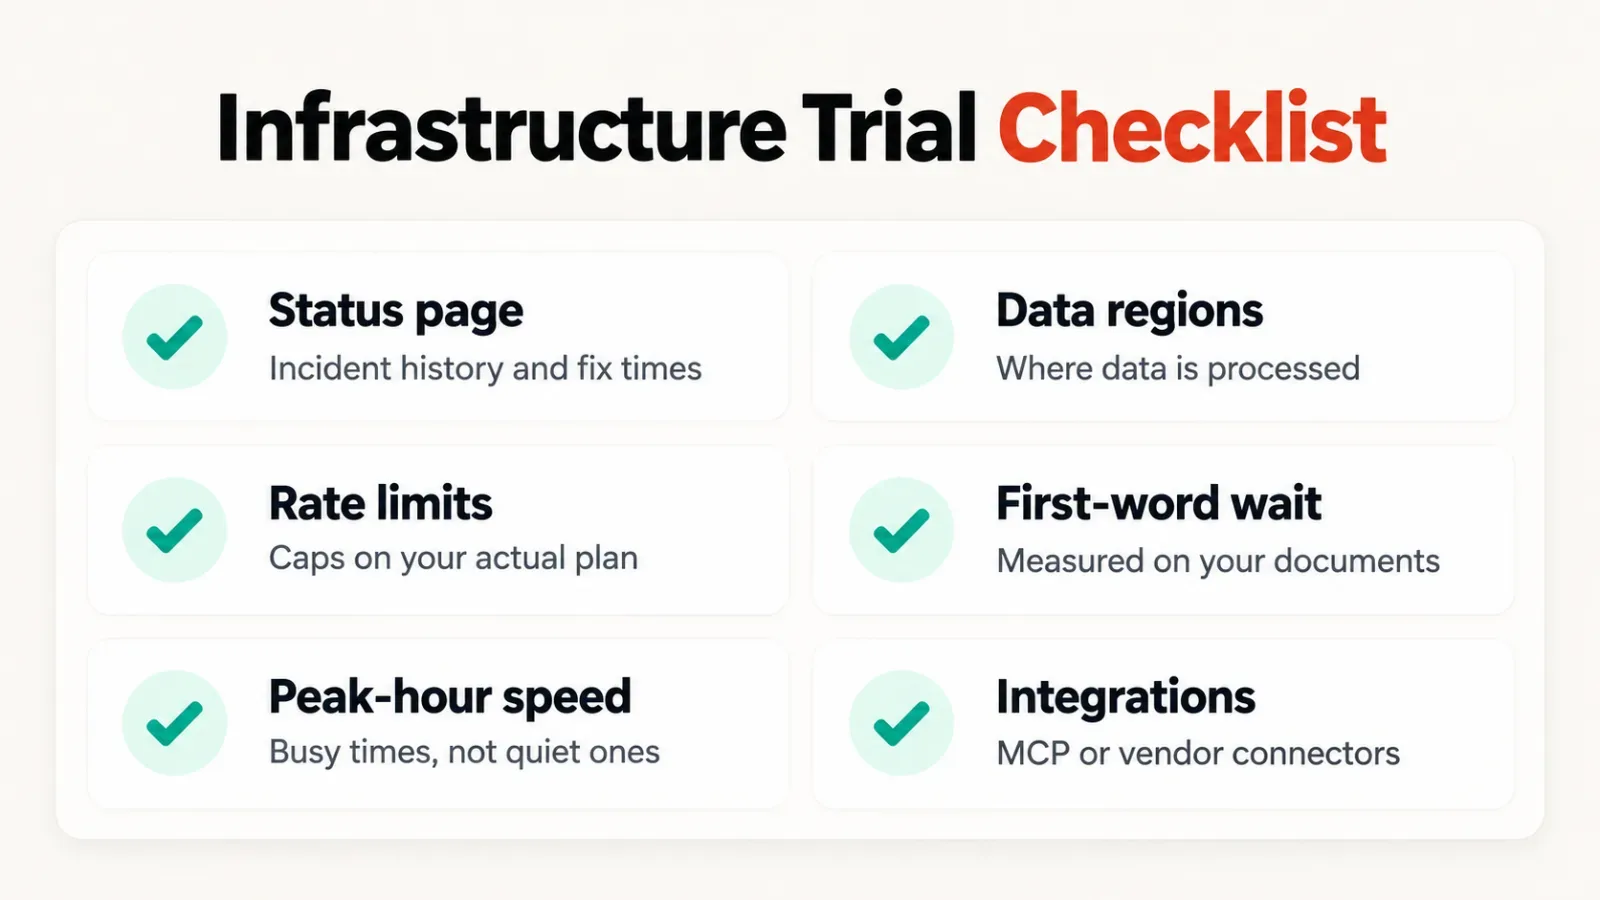
- A public status page with a history of incidents and how fast they were fixed.
- The regions where your data is processed and stored.
- The rate limits and usage caps on the plan you’d actually buy.
- The wait before the first word appears, measured on your own documents.
- Response times during your busiest hours, not only at quiet times.
- The way integrations connect, such as MCP or the vendor’s own connectors.
A tool with a strong model and no status page is a bet you can’t monitor. Once your criteria are set, browse the full A to Z directory of AI tools to build a shortlist.
The Next Competitive Edge Isn’t Another Model
The AI industry moves fast enough that today’s breakthrough becomes tomorrow’s baseline. Reasoning improves, costs fall and open-source models catch up, so features that once set products apart turn into expectations.
Buyers then stop asking who has the smartest model. They ask which tool fits their workflow, answers instantly, stays up during peak demand and feels dependable enough for everyday work.
Model architecture doesn’t decide those qualities. Engineering decisions made long before the first token do.
Internet infrastructure spent years as a supporting character in the technology story. As AI tools grow more connected, more global and more embedded in daily work, networking stops hiding in the background and becomes part of the product.
Behind every polished AI interface sits a stack of networks, servers, routing decisions and IP addresses that rarely gets any credit. Without it, even the most capable model would have nothing to say.
Frequently asked questions
Is AI Infrastructure the Same as Cloud Computing?
No, cloud computing is one part of AI infrastructure. AI infrastructure also covers the GPUs for training and inference, the retrieval systems that feed a model its context, and the networks and IP addresses that connect them. Many AI tools rent most of those parts from cloud providers rather than owning them.
What’s the Difference Between Training and Inference Infrastructure?
Training infrastructure builds the model, using large GPU clusters that run for weeks or months on huge datasets. Inference infrastructure runs the finished model every time someone sends a prompt, so it has to be fast, close to users and available around the clock. Most AI tools in a directory never train a foundation model: they pay for inference.
Why Do AI Tools Slow Down at Busy Times?
AI tools slow down at peak hours because inference servers have a fixed amount of GPU capacity. When requests outpace it, they queue, and rate limits start rejecting some of them.
Does an AI Tool Need IPv6?
An AI tool benefits from IPv6, but it can’t drop IPv4 yet. Plenty of users and corporate networks still connect over IPv4 only, so public services run both. That’s why IPv4 leasing still matters for AI companies expanding into new regions.