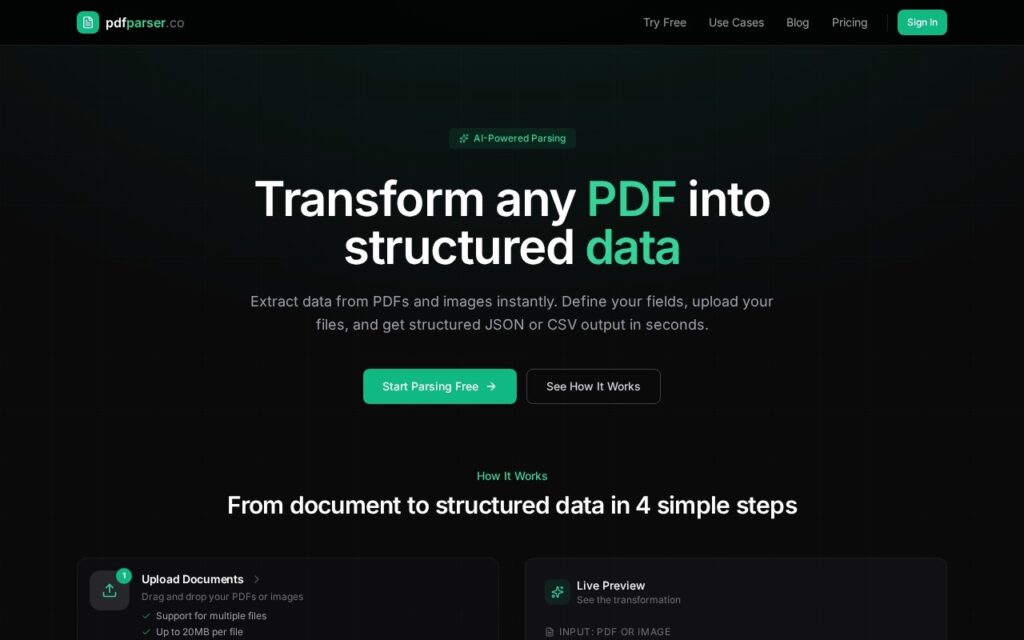
PDF Parser extracts structured data from PDFs and images using GPT-4-class vision models for context-aware extraction: define the fields you want, upload a file, and get JSON or CSV output back in under 30 seconds. The AI engine adapts to both structured forms and unstructured free-text layouts without requiring templates – understanding document context rather than relying on predefined field positions the way traditional rule-based PDF parsers do.
Not requiring templates is the meaningful technical difference from older document-extraction tools – rule-based parsers typically need a template defining exactly where each field sits on a specific document layout, which breaks the moment a vendor changes their invoice format or you need to process documents from multiple different sources with different layouts. A context-aware AI engine that understands what it’s looking at, rather than only where things sit on a known template, handles that layout variation without requiring a new template for every document format.
PDF Parser supports PDFs and multiple image formats (JPEG, PNG, WebP, TIFF, BMP, GIF), batch processing up to 20MB per file, custom field definitions with multiple data types, and secure handling where documents aren’t permanently stored. API access is included on all plans. A free trial covers 20 pages with no credit card required; Starter runs $9/month (100 pages), Pro runs $29/month (500 pages, most popular), and Business runs $99/month (2,500 pages).