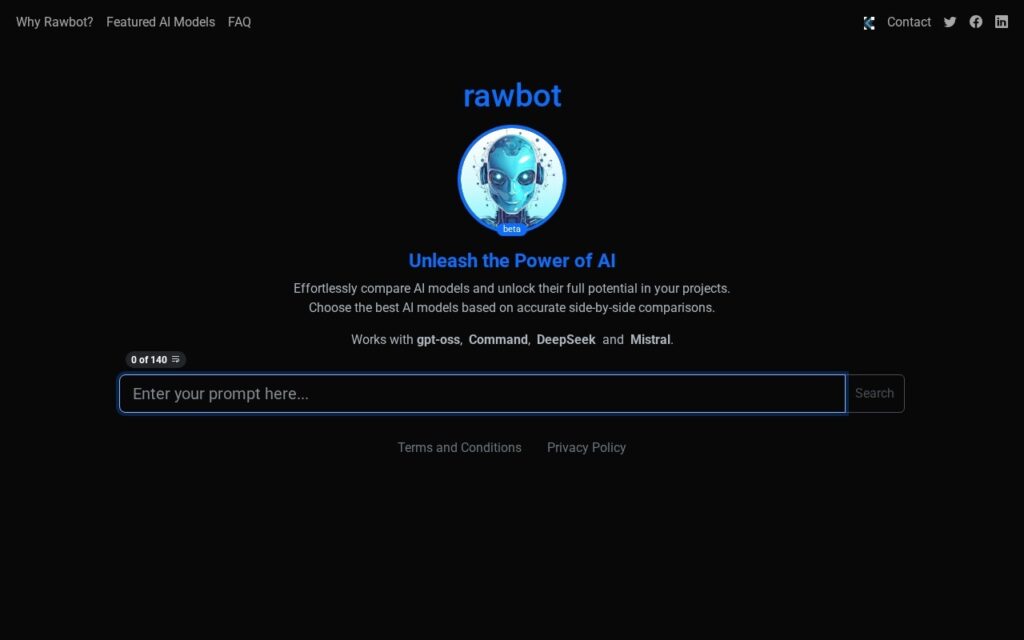

Rawbot compares AI language models side by side on the criteria that actually decide which one to use for a given project: performance, efficiency, suitability, and resource requirements. Coverage extends beyond the usual handful of flagship models to include less commonly compared options like Cohere’s Command R and AI21’s Jamba 1.5 Mini alongside mainstream models such as GPT-4o Mini.
The real value here is coverage breadth combined with customizable comparison criteria – developers choosing a model for a specific project care about different things (cost per token, latency, a specific benchmark) and a static leaderboard doesn’t answer that. Real-time updates keep the comparisons current as models get updated or replaced, which matters specifically because model rankings shift often enough that a comparison tool updated only occasionally goes stale fast.
Rawbot is free to use, aimed at developers and teams evaluating which AI model best fits their project’s speed, accuracy, and computational-efficiency requirements before committing to one.