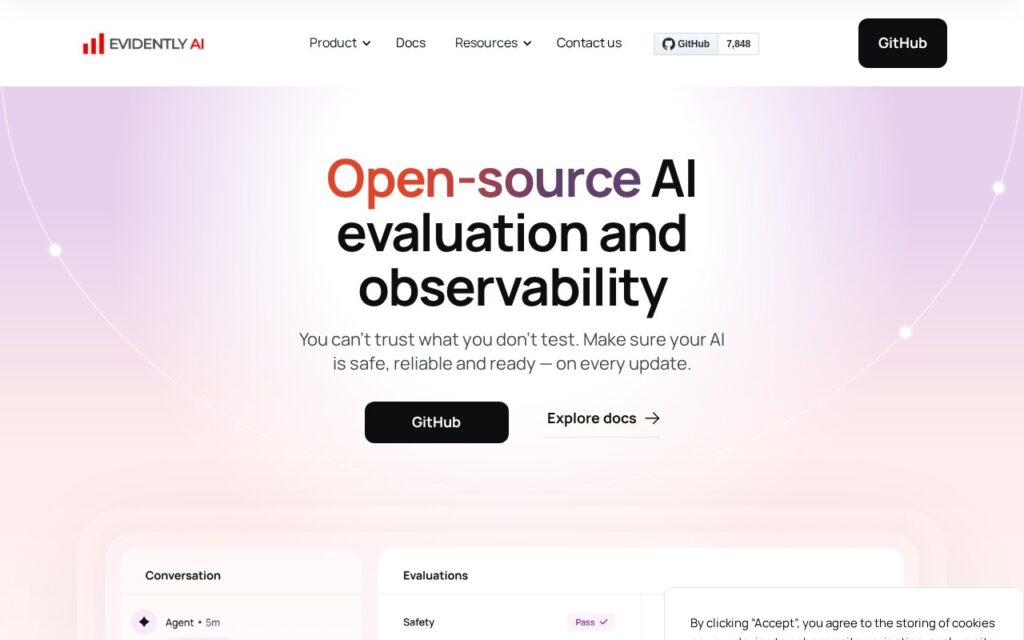

Evidently AI is an open-source framework for evaluating, testing, and monitoring LLM applications and machine learning models. It is released under the Apache 2.0 license and aims to keep AI systems “safe, reliable and ready – on every update.” Its main evaluation method is LLM-as-a-Judge, where a language model scores outputs, alongside custom checks built from any prompt, model, or rule.
Evidently AI ships 100+ built-in metrics covering hallucinations, factuality, toxicity, PII detection, retrieval quality, and adherence to guidelines. It also produces visual reports, generates synthetic data for edge-case and adversarial tests, and offers monitoring dashboards that track quality drift over time. It works with chatbots, RAG applications, AI agents, and traditional ML models.
Evidently AI is aimed at MLOps engineers, data scientists, and ML infrastructure teams, from startups to enterprises. The company’s site features testimonials from teams at DeepL, Wise, Flo Health, and PlushCare. The project has 7,500+ GitHub stars and 40M+ downloads.
How Evidently AI fits into an AI stack
Evidently AI works as the quality layer on top of your models: you run evaluations before release, then keep monitoring after launch. This suits teams that need repeatable tests rather than manual spot checks of model answers. For the hardware and services underneath, see our guide to AI infrastructure behind every AI tool.
If you are building automated pipelines around your models, compare options in our AI automation tools roundup. Self-hosting needs technical setup, so smaller teams should check whether they have the capacity to maintain it.